

Sometimes the most useful thing an expert can say is “I don’t know.” When they say it, it’s neither evasive nor performative; it is specific, and it means something like: I understand this well enough to know what is missing, and I can tell you what would settle it.
Large language models are poor at that particular sentence. They are fluent well past the point where their grip on a particular body of work runs out, which is why they can seem impressive and naive at the same time. They produce the texture of expertise before they have the judgement that makes expertise worth trusting.
This is not an argument that they are useless. They are extremely useful. They draft, summarise, translate, explain, compare, search, code, and compress large volumes of material into something a person can act on. But there is a difference between producing expert-shaped language and being expert in a particular body of work, and the gap is not only factual. It is also about what the model knows about its own knowledge, about how a piece of work is meant to proceed, and about which situation it is actually in.
Fluency is a weak signal of expertise
A good model answer tends to have the rhythm of competence. It gives structure, names the concepts, balances the objections, and reads like something written by someone who has seen the terrain before.
In ordinary life, fluency is a reasonable signal of expertise, because in people it’s usually expensive to acquire. Someone who can explain a subject clearly has often had to understand it first. Language models make fluency cheap, and in doing so they break the link between the signal and the thing it used to indicate.
There is a well-known demonstration of how loose that link can be even in trained humans. In 2001 three researchers at Bordeaux gave 54 oenology undergraduates a white wine that had been dyed red with an odourless colourant, and asked them to describe it. The students reached for the red-wine vocabulary: tannic, blackcurrant, and the rest. The descriptions were fluent, trained and confident, and they tracked the colour of the liquid rather than its smell. The study is often retold as proof that wine experts are frauds, which overstates it; the participants were students, and the finding concerns vision dominating olfaction. What it does show however is that a well-drilled descriptive vocabulary can run on cues that have nothing to do with the thing being described.
Experts do not only answer well. They know where the answer came from, what would change it, which assumptions are fragile, which distinctions matter, which evidence is stale, and which parts of the problem are still open. A general model, without support, has none of that relationship to your work. It may know the vocabulary of a field without knowing the state of your project. It may know the general pattern without knowing the exception that governs this case. It may recall an earlier conversation without knowing whether what was said then still holds. The practical risk is that a premature answer arrives sounding settled.
What the Dunning-Kruger effect actually shows
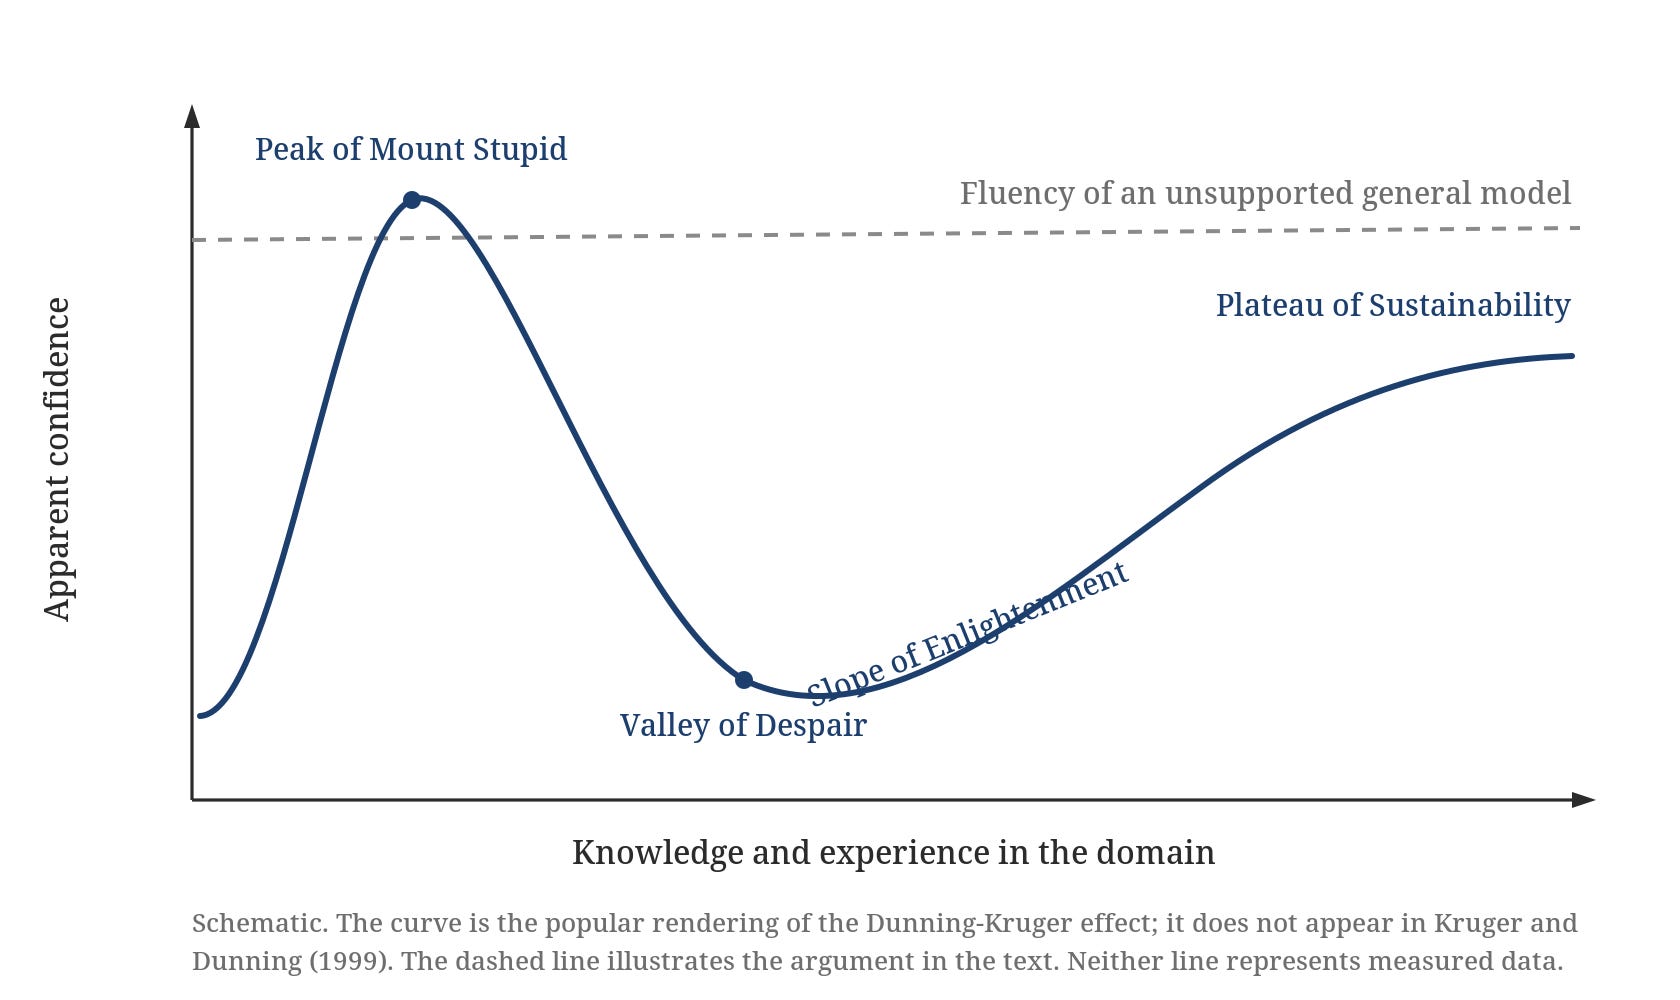
The popular version of Dunning-Kruger is the curve above: confidence spikes early at Mount Stupid, collapses into the Valley of Despair, then climbs slowly as real competence arrives. It’s a good joke and a poor description of the research. Kruger and Dunning’s 1999 paper contains nothing resembling that curve. They split participants into quartiles by test performance and plotted two lines: perceived ability, which was fairly flat and sat above the midpoint for nearly everyone, and actual ability, which rose steeply. The bottom quartile overestimated itself by the widest margin; the top quartile slightly underestimated itself. There is no peak and no valley.
The effect has also been argued down since. Gignac and Zajenkowski (2020) show that most of what the standard analysis measures can be produced by the better-than-average effect combined with regression to the mean, without any specific metacognitive failure among the least skilled. The curve is a fluent, satisfying account of a paper that most people quoting it have not read, which makes it a reasonable illustration of the problem it is usually used to describe.
What survives, and is the part worth carrying into this argument, is the metacognitive claim. Judging your own performance draws on some of the same knowledge as performing well. If you do not know the standards of a field, you cannot apply them to your own output. You lack the answer, and you also lack the means of assessing it.
That version transfers to language models, and there is a well-documented example of the transfer. In 2023 a New York lawyer filed a brief in Mata v. Avianca containing six judicial decisions that did not exist. The fabricated citations are now the most worn anecdote in writing about AI. What is less often quoted is what happened when he began to have doubts. He asked ChatGPT whether the cases were real, and it told him they were. He asked it to produce the full text of one, and it obliged. The verification and the claim came out of the same process, so of course they agreed, and his check had no independent purchase on the answer it was checking.
That is the shape of the problem. A model can produce a plausible answer without holding the surrounding discipline that would tell it whether the answer has been earned, and its assessment of the answer is drawn from the same distribution that produced it. The dashed line in the diagram is the practical consequence: apparent confidence stays roughly flat and high, whatever the model’s actual purchase on the specific problem.
Kinds of not-knowing, and what next-token prediction does with them
“I don’t know” is not one statement, and the machine learning and statistics literature separates the kinds because they call for different responses.
Aleatoric uncertainty is irreducible noise in the process being modelled: a fair die, or an instrument with genuine jitter. More data will not remove it, because it is a property of the world rather than of your ignorance. Epistemic uncertainty is the reducible kind, arising from not having seen enough. It is what a further measurement, a better dataset, or an experiment can shrink. Heteroscedastic uncertainty is aleatoric noise whose size varies with the input, as against homoscedastic noise, which is constant across the range. A sensor may be precise in the middle of its range and vague at the extremes. Any system that reports one confidence figure for all inputs is assuming homoscedasticity, whether or not it says so. Beyond these, applied work cares about distributional shift, where the input is unlike anything in training and the model’s training error says nothing useful about its error here, and about ambiguity, where the question admits several readings and the uncertainty concerns what is being asked rather than what is true.
These distinctions are not academic. In 2020 Google Health published a study of what happened when its diabetic retinopathy screening model met real clinics in Thailand. In the laboratory the model detected signs of the disease with better than 90% accuracy, which the team described as specialist level. In eleven clinics it rejected more than a fifth of the photographs outright as ungradable, because nurses were photographing dozens of patients an hour in rooms with no dedicated lighting, and the images fell below the quality threshold the model had been trained on. Nurses were asked to retake pictures of eyes they could see perfectly well were healthy. Some patients were referred on unnecessarily. Slow connections meant uploads timed out while people waited.
Nothing was wrong with the 90% figure. It was measured on high-quality images of the kind the model was built for. What the single number could not express was that the model’s error profile varied enormously with the conditions of the clinic, and that in several of those clinics the inputs were unlike its training data in ways that made the laboratory figure inapplicable. One accuracy statistic was carrying heteroscedastic noise and distributional shift at the same time, and reporting neither.
An autoregressive language model does produce a probability distribution over the next token, and that distribution carries information bearing on several of these types at once. Low-entropy and high-entropy positions genuinely differ. Trained on enough human text, a model plausibly picks up regularities of hedging, of contested claims, and of domains where sources disagree, because the linguistic surface of uncertainty is in the data and predicting it well requires some sensitivity to it.
The difficulty is that none of these types is separately represented, and none of them is what the objective asks for. Next-token prediction asks how likely a token is to come next, not what kind of not-knowing is in play. The resulting entropy is a mixture. High entropy at a given position may mean the model does not know the fact, or that there are twenty equally good ways to phrase a fact it knows perfectly well. Separating uncertainty about meaning from uncertainty about wording is exactly what semantic entropy methods set out to do, by sampling several answers, clustering them by meaning, and measuring the spread over meanings rather than over strings (Farquhar and colleagues, Nature, 2024). That it works reasonably well suggests the underlying signal is partly there. That it has to be built deliberately suggests the base model does not hand it to you.
Post-training makes the reading harder still. Preference tuning shapes how confident an answer sounds, and how confident it sounds is only loosely coupled to the distribution underneath. A model can be well calibrated in its logits and badly calibrated in its prose, or the other way round.
So the honest position is that an autoregressive model very likely has some internal purchase on uncertainty, because uncertainty is a real structure in the data it is trained to predict. But nothing in the training makes that structure explicit, labelled, or separable, and nothing requires the model to consult it when deciding what to say. We usually cannot tell which kind of not-knowing is driving a given output, and in any usable sense neither can the model.
Expert uncertainty is specific
There is a cheap version of humility that appends “I may be wrong” to everything. That is a disclaimer rather than a judgement.
The expert version says which kind of not-knowing applies, and by implication what would resolve it. I don’t know, because we have not measured that yet. I don’t know, because the source is unreliable. I don’t know, because it depends on which definition we are using. I don’t know, because the result may not generalise beyond the tested case. I don’t know, because two explanations still fit the evidence.
The clearest statement of that last kind I know of was made on a conference call on the evening of 27 January 1986. Engineers at Morton Thiokol were arguing against launching Challenger the following morning. The forecast put the O-ring temperature at around 31 degrees Fahrenheit. The coldest previous shuttle launch had been at 53 degrees. Their recommendation, in the words the Rogers Commission recorded, was that “we should not fly outside of our data base, which was 53 degrees.”
That is a precise piece of epistemic reasoning. They were not claiming to know the seals would fail. They were saying that the evidence they had was collected inside a range, that the launch sat well outside it, and that nothing in their data licensed a prediction about what would happen there. It is distributional shift, identified in advance, by people who understood exactly which kind of not-knowing they were in.
NASA’s response was to treat the absence of proof as permission. Thiokol was asked to demonstrate that it was unsafe to fly, rather than to demonstrate that it was safe, and the burden quietly reversed. During the internal recess that followed, a senior vice president told the engineering vice president to take off his engineering hat and put on his management hat. The recommendation was withdrawn.
The engineers typed the uncertainty correctly and it changed nothing, because the process receiving it was not built to act on that kind of statement. This is worth holding onto when thinking about AI systems, since most of the design attention goes to making the model produce a better-calibrated statement, and much less to whether anything downstream can use one.
Context is not the same as the status of context
The common response to all this is to give the model more context, and that does help, sometimes a great deal. But context is not simply a larger volume of text. Expertise depends on knowing the standing of each piece of context: whether a fact is current, whether a note is still active or has been superseded, whether something is a direct observation, an inference, a preference, a convention, a hypothesis or a settled decision, whether a source has authority in this particular question, whether something that was true in an earlier phase of the work is still true, and whether a finding applies generally or only inside one narrow test.
IBM Watson for Oncology is the most expensive demonstration of what happens when that distinction is not made. The system was trained substantially on hypothetical cases constructed by a small number of clinicians at Memorial Sloan Kettering, rather than on real patients and their outcomes. Internal documents obtained by STAT in 2018 recorded staff describing “unsafe and incorrect” treatment recommendations. MD Anderson shelved its programme after spending tens of millions of dollars.
This is often read as a small-data problem. A more precise reading is that the training data had no status attached to it. A preference held by a particular team at a particular hospital in a particular year went in alongside established evidence, with nothing marking which was which, and emerged as a recommendation with the same weight. The system absorbed how one institution did things and could not distinguish it from what the field had settled. The standing of the context mattered more than its quantity.
A long-context model may have all of the relevant materials in front of it, and access is not the same as understanding. Neither is memory, and neither is retrieval. Even a complete transcript does not tell the model which parts of it still bind.
Real work is layered. It contains current goals, retired ideas, live hypotheses, old mistakes, personal preferences, institutional constraints, unwritten standards, half-settled decisions, and project-specific meanings that an outsider cannot infer from the vocabulary. A general model may read ‘we tried this before’ and treat it as a fact. An expert asks under what conditions it was tried, with what evidence, against what standard, and whether the conclusion still binds.
Knowing what the rules are for
Experts know the rules, and more importantly they know what the rules are for. They know when a standard procedure should be followed exactly because improvisation is expensive, when a shortcut is harmless, when a convention is only a convention, when an apparent edge case is in fact the central case, and when departing from the rule is judgement rather than arrogance.
This is procedural knowledge rather than factual knowledge. A doctor knows the guideline and also knows when the patient does not fit it. An engineer knows the pattern and also knows when the abstraction has started to leak. A lawyer knows the process and also knows when the process is being used against its own purpose. A researcher knows the method and also knows when the measurement has quietly begun answering a different question.
This is difficult for a general model because the relevant judgement is usually not visible in the prompt. The model may know the method in general without knowing whether this situation is ordinary, exceptional, fragile, politically sensitive, experimentally unresolved, or downstream of an earlier decision that changes what counts as correct.
Memory can make a system more confidently wrong
Tools narrow the gap without closing it. Retrieval can find the document. Memory can recall the earlier decision. Skills, connectors and external tools can run a procedure. The harder question is what standing the recalled thing now has: whether it is still active, whether it was a temporary workaround, whether it was a rule, a preference, a constraint, a hypothesis or a one-off exception, whether it applies at this level of the work or only inside a narrower scope, and what follows later if we treat it as settled now.
Memory is contextual, and context is hierarchical. A fact sits inside a project, a project inside a goal, a goal inside a method, a method inside a set of standards, constraints, relationships and consequences. This is why “just give the model memory” is too simple an answer. Memory can make a system more continuous, and it can also make it more confidently wrong. A remembered detail stripped of its scope becomes a superstition. A past correction stripped of its reason becomes a brittle rule. A shortcut that worked once becomes a hidden failure mode somewhere else.
Part of expertise is carrying context forward without flattening it. The expert question is not only what do I remember, but what kind of thing is this memory, where does it sit in the work, and what does it license me to do next.
Working where the method runs out
Experts also know when the standard method has run out. Sometimes the rules work, sometimes they need careful application, sometimes they need bending, and sometimes there is no rule yet because the work is new.
A real expert can say that we do not know the right answer, but we understand the current state well enough to make the next responsible move. They can tell recklessness from necessary invention. They can see when a problem matters enough that waiting for certainty is itself a decision with costs. They can act under uncertainty without pretending it has gone.
We trust some people not only because they know what is already known, but because they can produce new knowledge: stand at the edge of the field, judge what is possible, and choose a next step that is provisional, disciplined and worth trying. That requires judgement about the state of the evidence, the cost of delay, the risk of acting, the reversibility of the decision, and the consequences of being wrong.
A general model can help here. It can map options, offer analogies, challenge assumptions and generate possibilities. But this kind of judgement is not the same as being creative on request. It involves knowing when creativity is called for, which constraints still bind, which may be questioned, and how to stay honest while moving. At the frontier the useful sentence is that we do not know yet, and this is the best next experiment, design, argument or intervention given what we understand now.
Different kinds of not-knowing require different actions
Once the type of uncertainty is identified, the response follows from it. If information is missing, search. If the source is unreliable, verify. If the intent is unclear, ask. If the evidence is genuinely ambiguous, keep the alternatives open rather than collapsing them. If the claim is high stakes, slow down. If the context is stale, refresh it. If the question is outside your competence, defer. If the method is failing, inspect the method. If the uncertainty cannot be closed yet, say so and say why.
The most instructive example of a profession learning this is British weather forecasting. On 15 October 1987 Michael Fish told viewers that a woman had rung the BBC to say she had heard a hurricane was on the way, and that they should not worry, because there wasn’t. That night a storm crossed southern England with gusts over 100 miles per hour. Twenty-two people died. Around a billion pounds of damage was done, and something like fifteen million trees came down. The Met Office still describes it as the worst storm to hit the country since 1703.
The forecasters were not simply wrong. The models had a deep depression; the disagreement was about where it would go, and the observations over the Atlantic were too sparse to settle it. What went out on air was a single confident statement standing in for a genuinely unresolved forecast. The uncertainty existed, and the format had nowhere to put it.
Two things changed afterwards. The first was investment in the inputs: more observations, and models whose global resolution improved from 150 kilometres to around 10. The Met Office now says its four-day forecast is as accurate as its one-day forecast was in 1987. Forecasting also moved to ensembles, running the model many times from slightly perturbed starting conditions and reporting the spread of outcomes rather than a single trajectory. That is why a British forecast now gives a 40% chance of rain at three o’clock, and why severe weather warnings are graded by likelihood as well as impact.
An entire profession rebuilt its methods and its public language so that uncertainty would survive contact with the audience instead of being flattened into a verdict. That change took a decade and a disaster to arrive, and it made forecasts harder to read at a glance while making them much more useful to act on.
This is where unsupported models struggle. They are optimised to continue the conversation rather than to maintain a disciplined account of what is known and how well. They answer when they should ask, summarise when they should verify, generalise when they should scope, follow a rule when they should question it, and improvise when they should stay inside the standard. Most models will say “I don’t know” when asked to. What they lack is the behaviour that makes the phrase informative: identifying which kind of uncertainty applies and then doing the thing that kind calls for.
What a general model needs in order to be useful in your work
A general model can be an excellent assistant, and it does not become expert in your work on its own. It needs current sources. It needs tools that inspect reality rather than rely on recall. It needs feedback loops, tests and provenance. It needs a project-specific record of what is active, what is retired, what is speculative and what has been verified. It needs people who correct it, and systems that stop fluent guesses from settling into unexamined assumptions.
Most of all it needs a way to distinguish “I can produce a plausible answer” from “this answer is authorised by the current state of the work.” Without that, a general model will remain unskilled and over-fluent in exactly the places where expertise matters. It may know the facts without knowing the state of the work, know the rule without knowing whether the rule applies here, recall the decision without its scope, run the tool without understanding what the result licenses, or invent something without knowing whether invention was needed.
This suggests that better expert systems will not come mainly from larger models with longer memories. They will come from models placed inside better epistemic scaffolding: retrieval, verification, task state, source discipline, typed uncertainty, tool use, review loops and human partnership. The Thai clinics needed a model that knew its accuracy figure did not apply in that room. Watson needed a record of which of its inputs were evidence and which were local habit. The Thiokol engineers needed a decision process that could receive a well-typed statement of uncertainty without inverting the burden of proof. None of those gaps would be closed by a larger model.
From answering questions to working alongside
The more useful systems will not simply answer more questions. They will get better at recognising what kind of question they are being asked: when to answer directly and when to inspect, when to generalise and when to preserve a distinction, when to use memory and when to distrust it, when to follow the procedure and when to challenge it, when to proceed and when to ask, and when a confident answer would help as against when it would misrepresent the state of the work.
That describes something closer to a working colleague than an oracle: a system that helps a person think, test, remember, challenge and decide without pretending that every uncertainty has already been resolved. The short expert sentence is still sometimes “I don’t know.” The fuller version is: I don’t know yet, here is the kind of uncertainty this is, here is where we are in the work, here is what would reduce it, and here is what we can responsibly do next. Building a system that can produce that sentence honestly is a different engineering problem from building one that writes well.
References
Kruger, J. and Dunning, D. (1999). Unskilled and unaware of it: how difficulties in recognizing one’s own incompetence lead to inflated self-assessments. Journal of Personality and Social Psychology, 77(6), 1121–1134.
Gignac, G. E. and Zajenkowski, M. (2020). The Dunning-Kruger effect is (mostly) a statistical artefact: valid approaches to testing the hypothesis with individual differences data. Intelligence, 80, 101449.
Morrot, G., Brochet, F. and Dubourdieu, D. (2001). The color of odors. Brain and Language, 79(2), 309–320.
Farquhar, S., Kossen, J., Kuhn, L. and Gal, Y. (2024). Detecting hallucinations in large language models using semantic entropy. Nature, 630, 625–630.
Beede, E. et al. (2020). A human-centered evaluation of a deep learning system deployed in clinics for the detection of diabetic retinopathy. CHI ‘20.
Ross, C. and Swetlitz, I. (2018). IBM’s Watson supercomputer recommended “unsafe and incorrect” cancer treatments. STAT, 25 July.
Report of the Presidential Commission on the Space Shuttle Challenger Accident (1986), chapter 5.
Mata v. Avianca, Inc., 678 F. Supp. 3d 443 (S.D.N.Y. 2023).
Met Office (2017). 30th anniversary of the 1987 storm.