


A technician hears a pump running wrong before any alarm trips, eases back the load, and the bearing that would have failed on the next shift never gets the chance. An analyst re-runs a passing sample because one peak looks off, and the drift is caught two days before it reaches a batch record. A nurse holds a step on a clinical pathway for a beat longer than the protocol asks, because something in the patient’s colour says wait.
Ask any of them to explain, and they will offer something plausible, then trail off. The explanation is not the knowledge. The knowledge sits underneath it, built from years of shifts, samples, and patients, and it decides outcomes daily. No one can write it down, and every organisation runs on it.
Michael Polanyi named this problem in 1958. By 1966 he had compressed it into eight words: ‘We can know more than we can tell.’ Gilbert Ryle had already split knowing-how from knowing-that; Hubert Dreyfus used the distinction to argue that expertise cannot be reduced to rule-following; Harry Collins showed that much of it transfers only through situated practice, never through instruction alone.
Organisational theorists then explained why the problem matters commercially. Knowledge that resists articulation also resists copying, which is why the knowledge-based view of the firm treats tacit knowledge as the root of durable advantage. A rulebook can be leaked. A veteran operator’s ear for a failing bearing cannot.
Successive AI approaches have struggled with the same practical limit. Expert systems asked specialists to state their rules and received post-hoc rationalisations. Machine learning could infer patterns from recorded data, but it struggled where decisive judgements or cues were never observed. Retrieval-augmented generation connects models to documents, while the decisive knowledge may never have entered one. The recurring limitation is practical: the evidence required to represent the judgement is often missing.
We have spent the past several months working on this problem. The result is a paper, Tacit Fragments: Operationalising Tacit Knowledge as a Governed Memory Layer for Agentic AI, and Metis, an open reference architecture that implements it. The full paper accompanies this post as a PDF.
Agents now sit inside the work, where tacit knowledge lives
Agentic AI did not solve the epistemological problem. It changed the practical conditions around it.
Earlier systems sat outside the work. An agent sits inside it. It reads the work-order tool, the batch record, the case file; it acts through the same systems the worker uses; it maintains memory across episodes; and it can ask a question at the moment the answer is cheapest to give. That combination makes partial, situated capture more practical than it was. An agent embedded in a workflow can notice a pattern worth investigating, ask one small question at a natural pause, store the answer with its provenance, and retrieve it later only under similar conditions. None of this articulates tacit knowledge in full. All of it changes what is practically possible.
It also raises the stakes. Watch anyone do skilled work and the same loop repeats. The worker observes a state, takes an action, and sees the outcome. Experience can alter several points inside this loop. The novice takes the action the procedure specifies. The expert notices cues the manual never mentions, and in some states takes a different action that no written rule calls for. A difference between specified and enacted action can be one useful signal of tacit practice. A foundation-model agent dropped into a real workflow starts on the novice’s side of the gap while sounding like an expert, and its fluent language can conceal the absence of situated judgement.
So the practical design question is narrower. Which aspects of tacit practice leave enough behavioural traces, and carry enough contextual conditions, to become computational artefacts under real accountability?
From tacit knowledge to tacit practice to tacit fragment
Answering that question forced us to separate three terms that casual usage runs together.
Tacit knowledge is the experience-based know-how that shapes competent action but cannot be fully expressed as rules, facts, or instructions at the moment it is used. The operator’s internalised sense that a pump is beginning to fail is tacit knowledge. It stays in the operator’s head, and any verbal account of it is incomplete.
Tacit practice is how that knowledge shows up in observable work. Easing back the load before the alarm trips is tacit practice. The knowledge remains hidden; the practice appears in what the expert notices, when they act and how they interpret the situation. Divergence from procedure is one possible signal, not the definition of expertise.
A tacit fragment is a bounded, structured record of one such piece of practice. A record stating that high-load operation combined with low-frequency vibration warrants reducing throughput is a tacit fragment, but only if it also carries where it came from, when it applies, how strong the evidence is, and who has reviewed it.
We chose the word fragment deliberately. A fragment is a piece, and it admits to being a piece. It never claims to contain the worker’s expertise, and it is never treated as fact. The word guards against the two oldest mistakes in this field. One treats tacit knowledge as impenetrable mystique that computation must never touch; the other treats it as undocumented explicit knowledge, a hidden rulebook waiting for the right extraction method. Both are wrong. Some aspects of skilled practice can be partially surfaced through careful observation and elicitation, and what surfaces is not the knowledge itself. It is a partial, situated representation that becomes useful only when it stays tied to its conditions, its source, and its validation status.
Identify, codify, insert, and what each phase loses
Operationalising tacit knowledge means moving it through three phases, and each one loses something.
Identification asks which aspects of practice actually matter for performance. This is harder than it sounds, because the causes of skilled action are opaque even to the actor. Experts act well without knowing exactly why, and when asked, they may supply a confident explanation that was not the real basis of their action. Structured elicitation methods from cognitive task analysis, the Knowledge Audit and the Critical Decision Method among them, surface far more than open-ended questioning, but no interview can stand alone. Identification only becomes reliable through triangulation. Compare what people say, what they do, and what happens as a result.
Codification translates what was identified into a form a system can store and inspect. The translation is never neutral. When a worker says a sample ‘looks wrong’, the phrase carries meaning only against a background of experience and shared context, and Quine’s old point about translation applies with full force. Meaning does not move cleanly between systems of representation. Codification therefore has to preserve the conditions under which the judgement was made, the cues that supported it, and the evidence connecting it to outcomes, all in a controlled vocabulary that workers, reviewers, and agents read the same way.
Insertion puts the representation to work inside an agent, and this is where careful capture fails most often. A statement like ‘wait longer when the material looks unstable’ is useful in one setting and dangerous in another. If the agent retrieves it too broadly, treats it as a rule, or applies it without checking context, faithfully captured expertise becomes a source of error. Insertion demands strict applicability conditions, confidence boundaries, and escalation rules, so the agent treats the fragment as situated guidance and never as universal instruction.
Loss at every phase is a defining property of the problem, not a flaw to engineer away, and it dictates the architecture. Since fragments are partial by nature, everything depends on governing how they are used.
Tacit as a proposed fourth memory stratum
Agent systems commonly distinguish three forms of memory. Procedural memory records what the agent was supposed to do, the skills, routines, and action policies. Semantic memory holds facts, concepts, and ontologies. Episodic memory records what actually happened, under what conditions, with what result. Each is useful, but bounded traces of expert practice may span them without being adequately governed by any one.
That residue is what a fourth layer must carry. We call it Tacit.
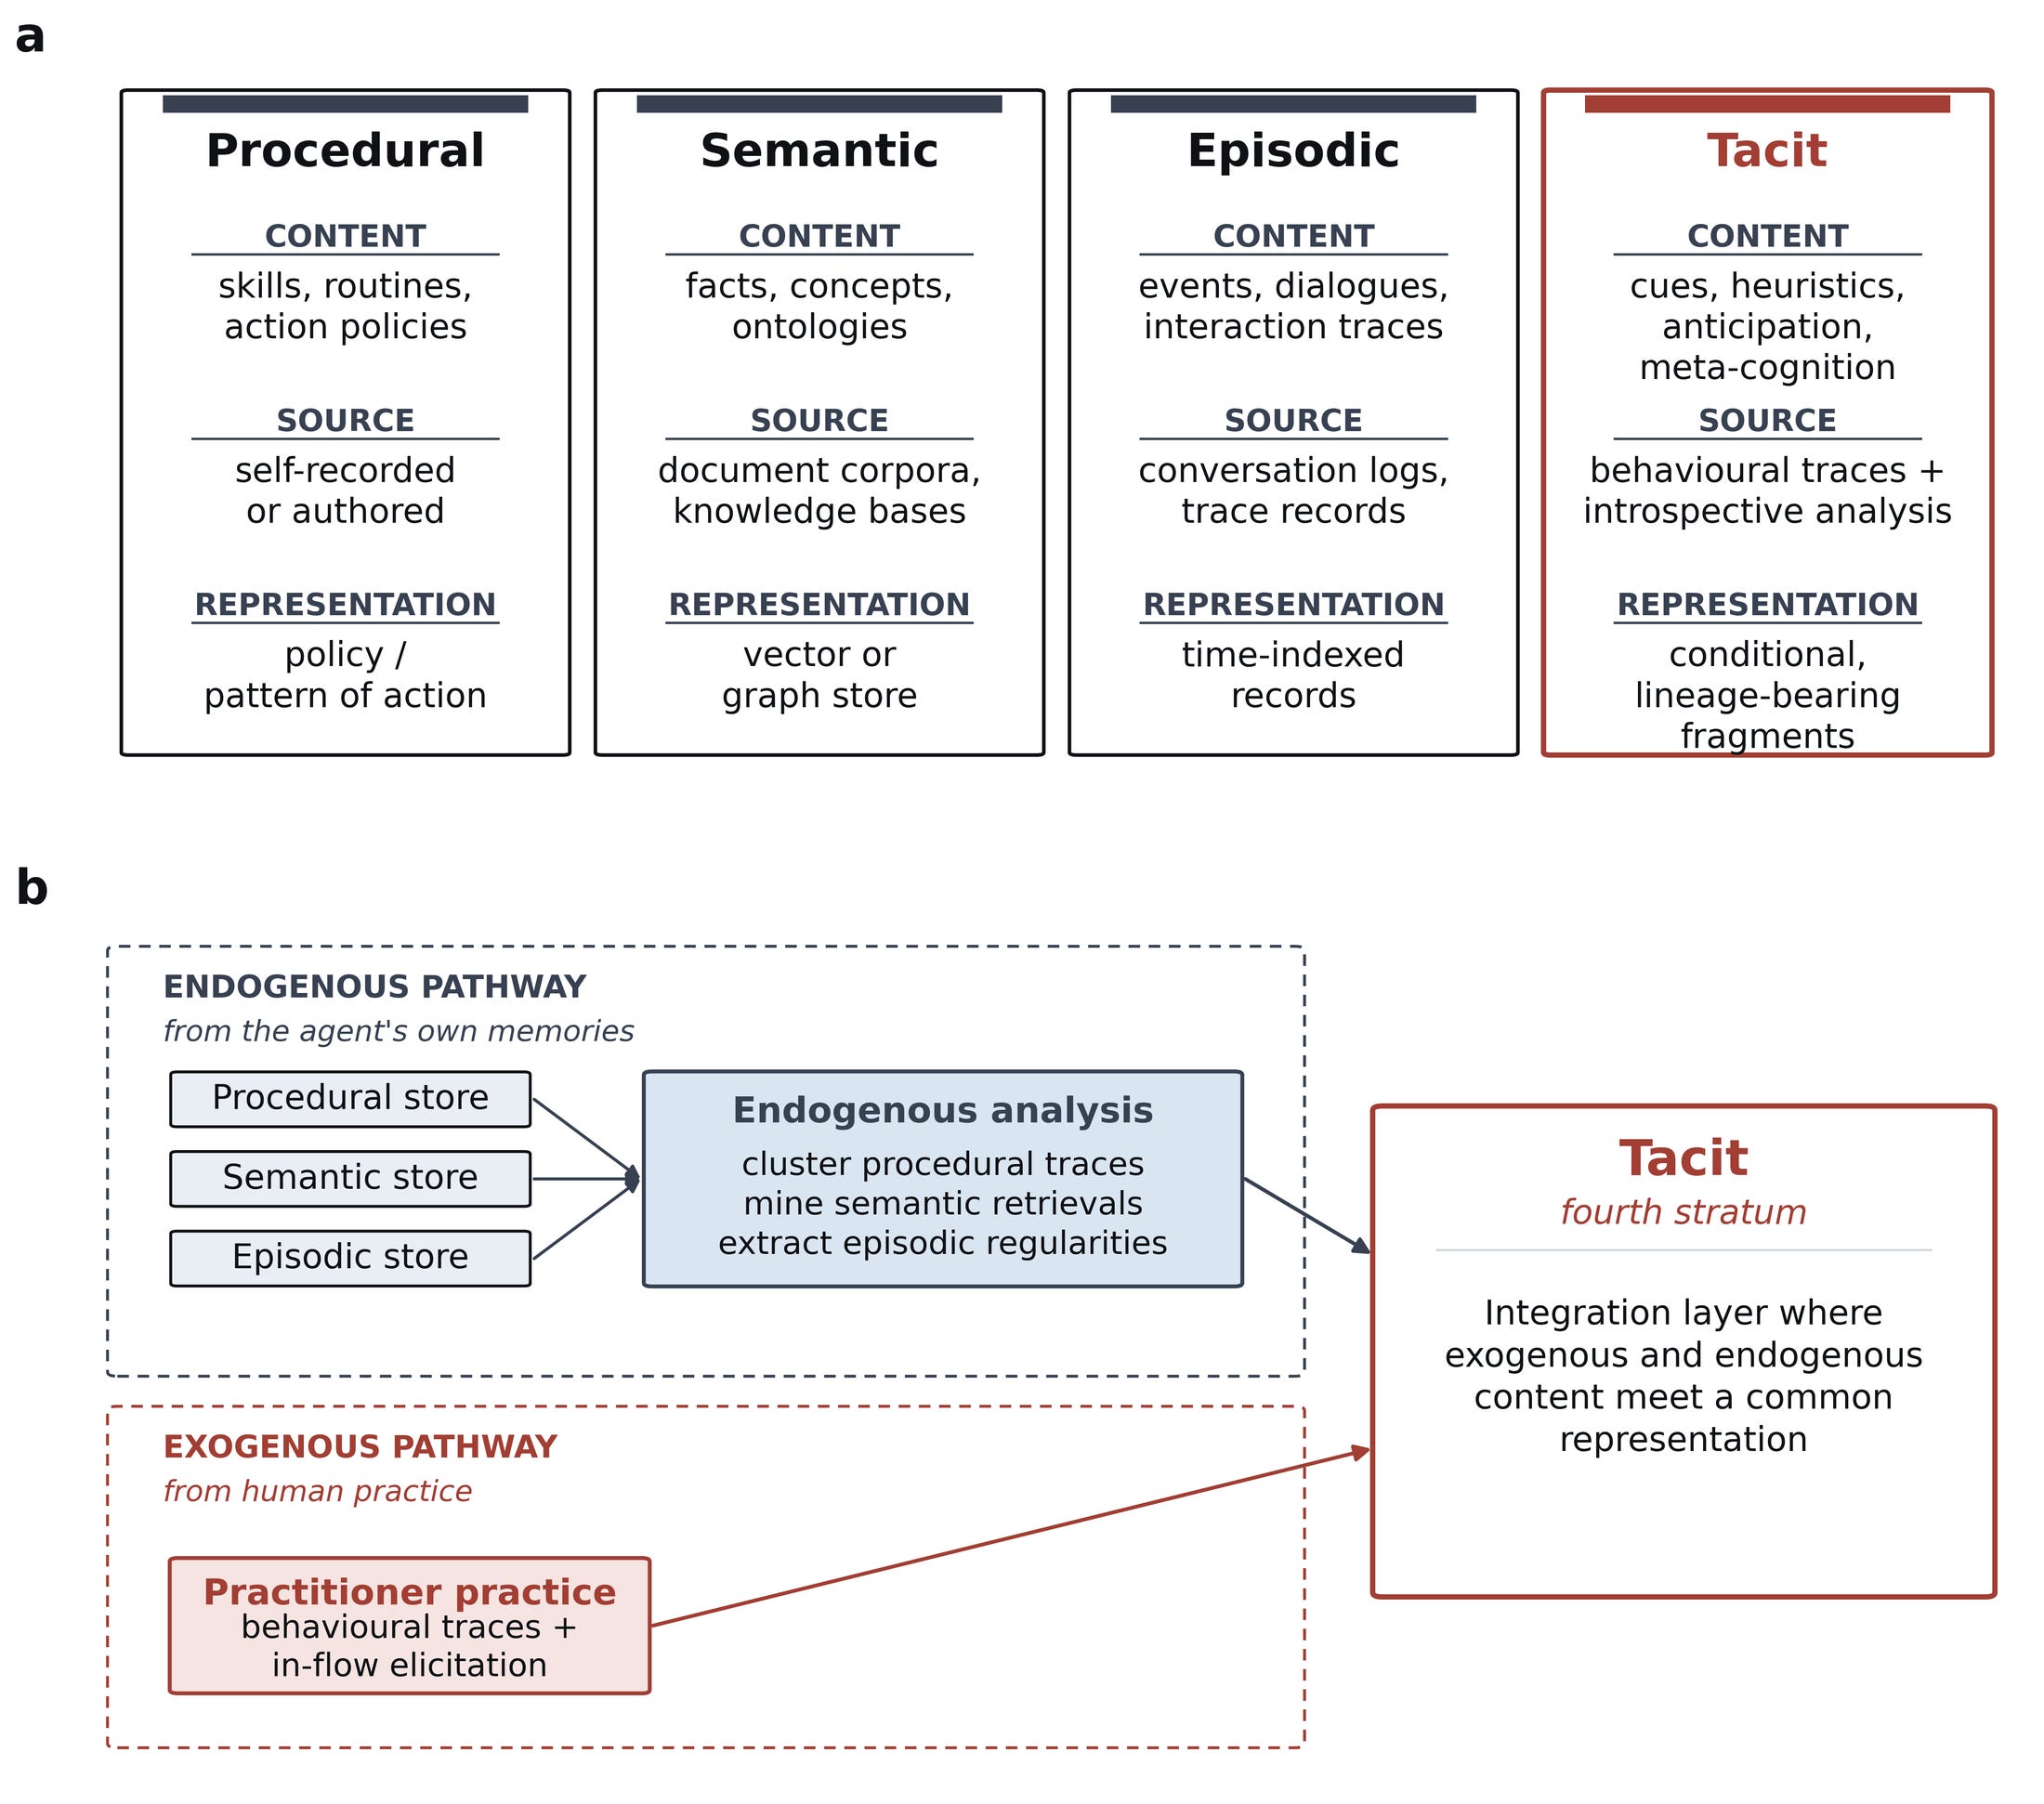
Every entry in the layer is a governed tacit fragment with a fixed schema rather than free text.
f = ⟨ content, provenance, conditions, confidence, authority, validation-state ⟩
Content holds the cue or adjustment itself, which need not be text. It may be a worker’s phrasing, an annotated exemplar, or a signal representation. Provenance records the exact origin. Conditions restrict where the fragment applies, because a cue that is reliable under one set of circumstances misleads under another. Confidence grades the evidence. Authority sets how much operational weight an agent may give it. Validation-state records its human review status.
We treat Tacit as a distinct operational stratum because every entry is governed by a specific contract. No entry may influence action except through that contract. Existing stores can carry these properties; Metis makes them mandatory and action-governing. A training example is treated as ground truth. A tacit fragment is neither. It is situated guidance an agent may use exactly where it applies, and must stop using the moment it does not.
The paper proposes two pathways into the layer. The exogenous pathway, the primary focus of the paper, captures fragments from observed human practice. The endogenous pathway turns the same diagnostic inward. It compares what the agent was supposed to do against what it actually did across its own procedural and episodic memory, computing a structured difference signal (Δ = enacted ⊖ specified) and surfacing deviations that recur and stabilise. Endogenous candidates enter the layer strictly as hypotheses, flagged with machine provenance and held to a higher evidence bar, because a stable deviation may encode competence, or it may encode a glitch, a contaminated input, or a statistical artefact, and the loop that produced the deviation cannot make that distinction itself.
Seventeen kinds of tacit knowledge, from sensory cues to handover rhythms
A sensory cue, a troubleshooting heuristic, the rhythm of a team handover, and the judgement of when to escalate are all tacit competence, and they cannot be captured, validated, or inserted the same way. The paper develops a working taxonomy of seventeen categories (K1 to K17) across six domains, from procedural-embodied through social-normative, each mapped to the capture and validation choices it demands.
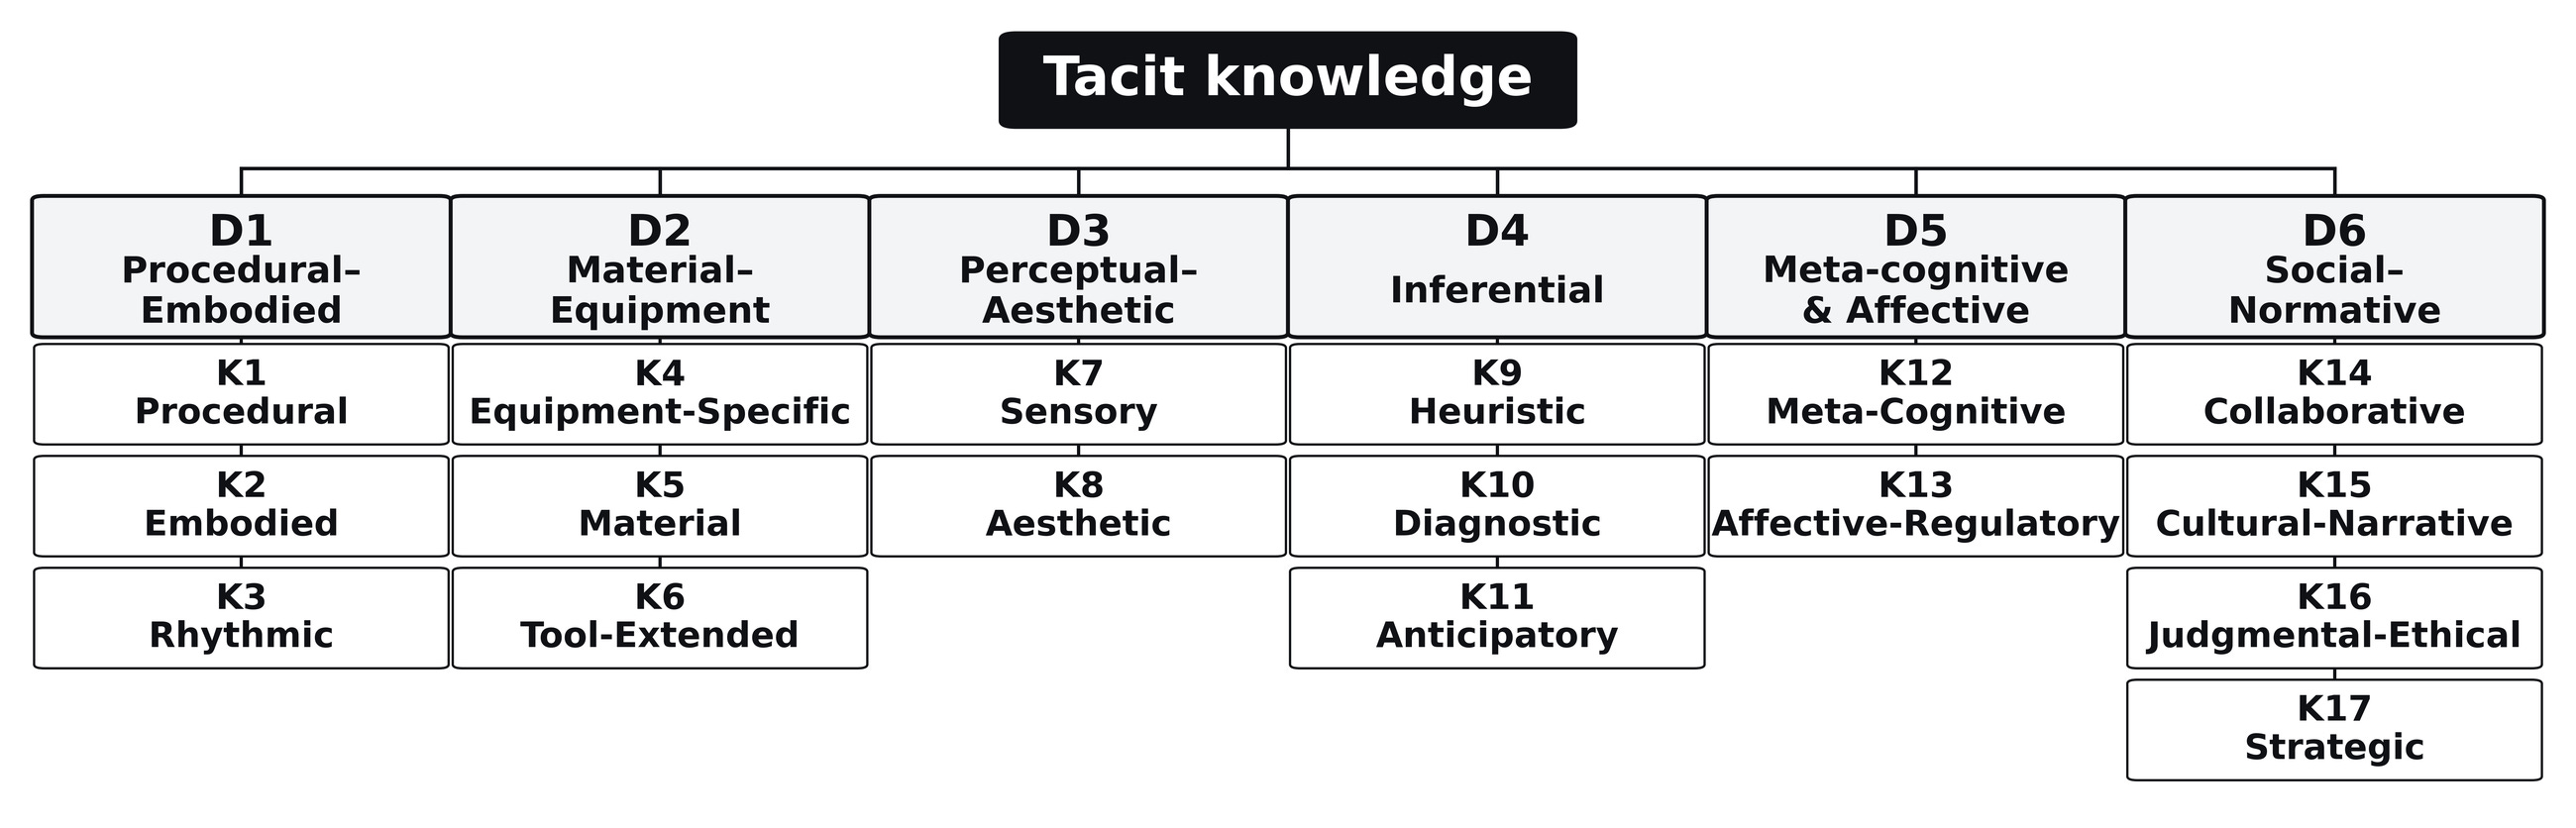
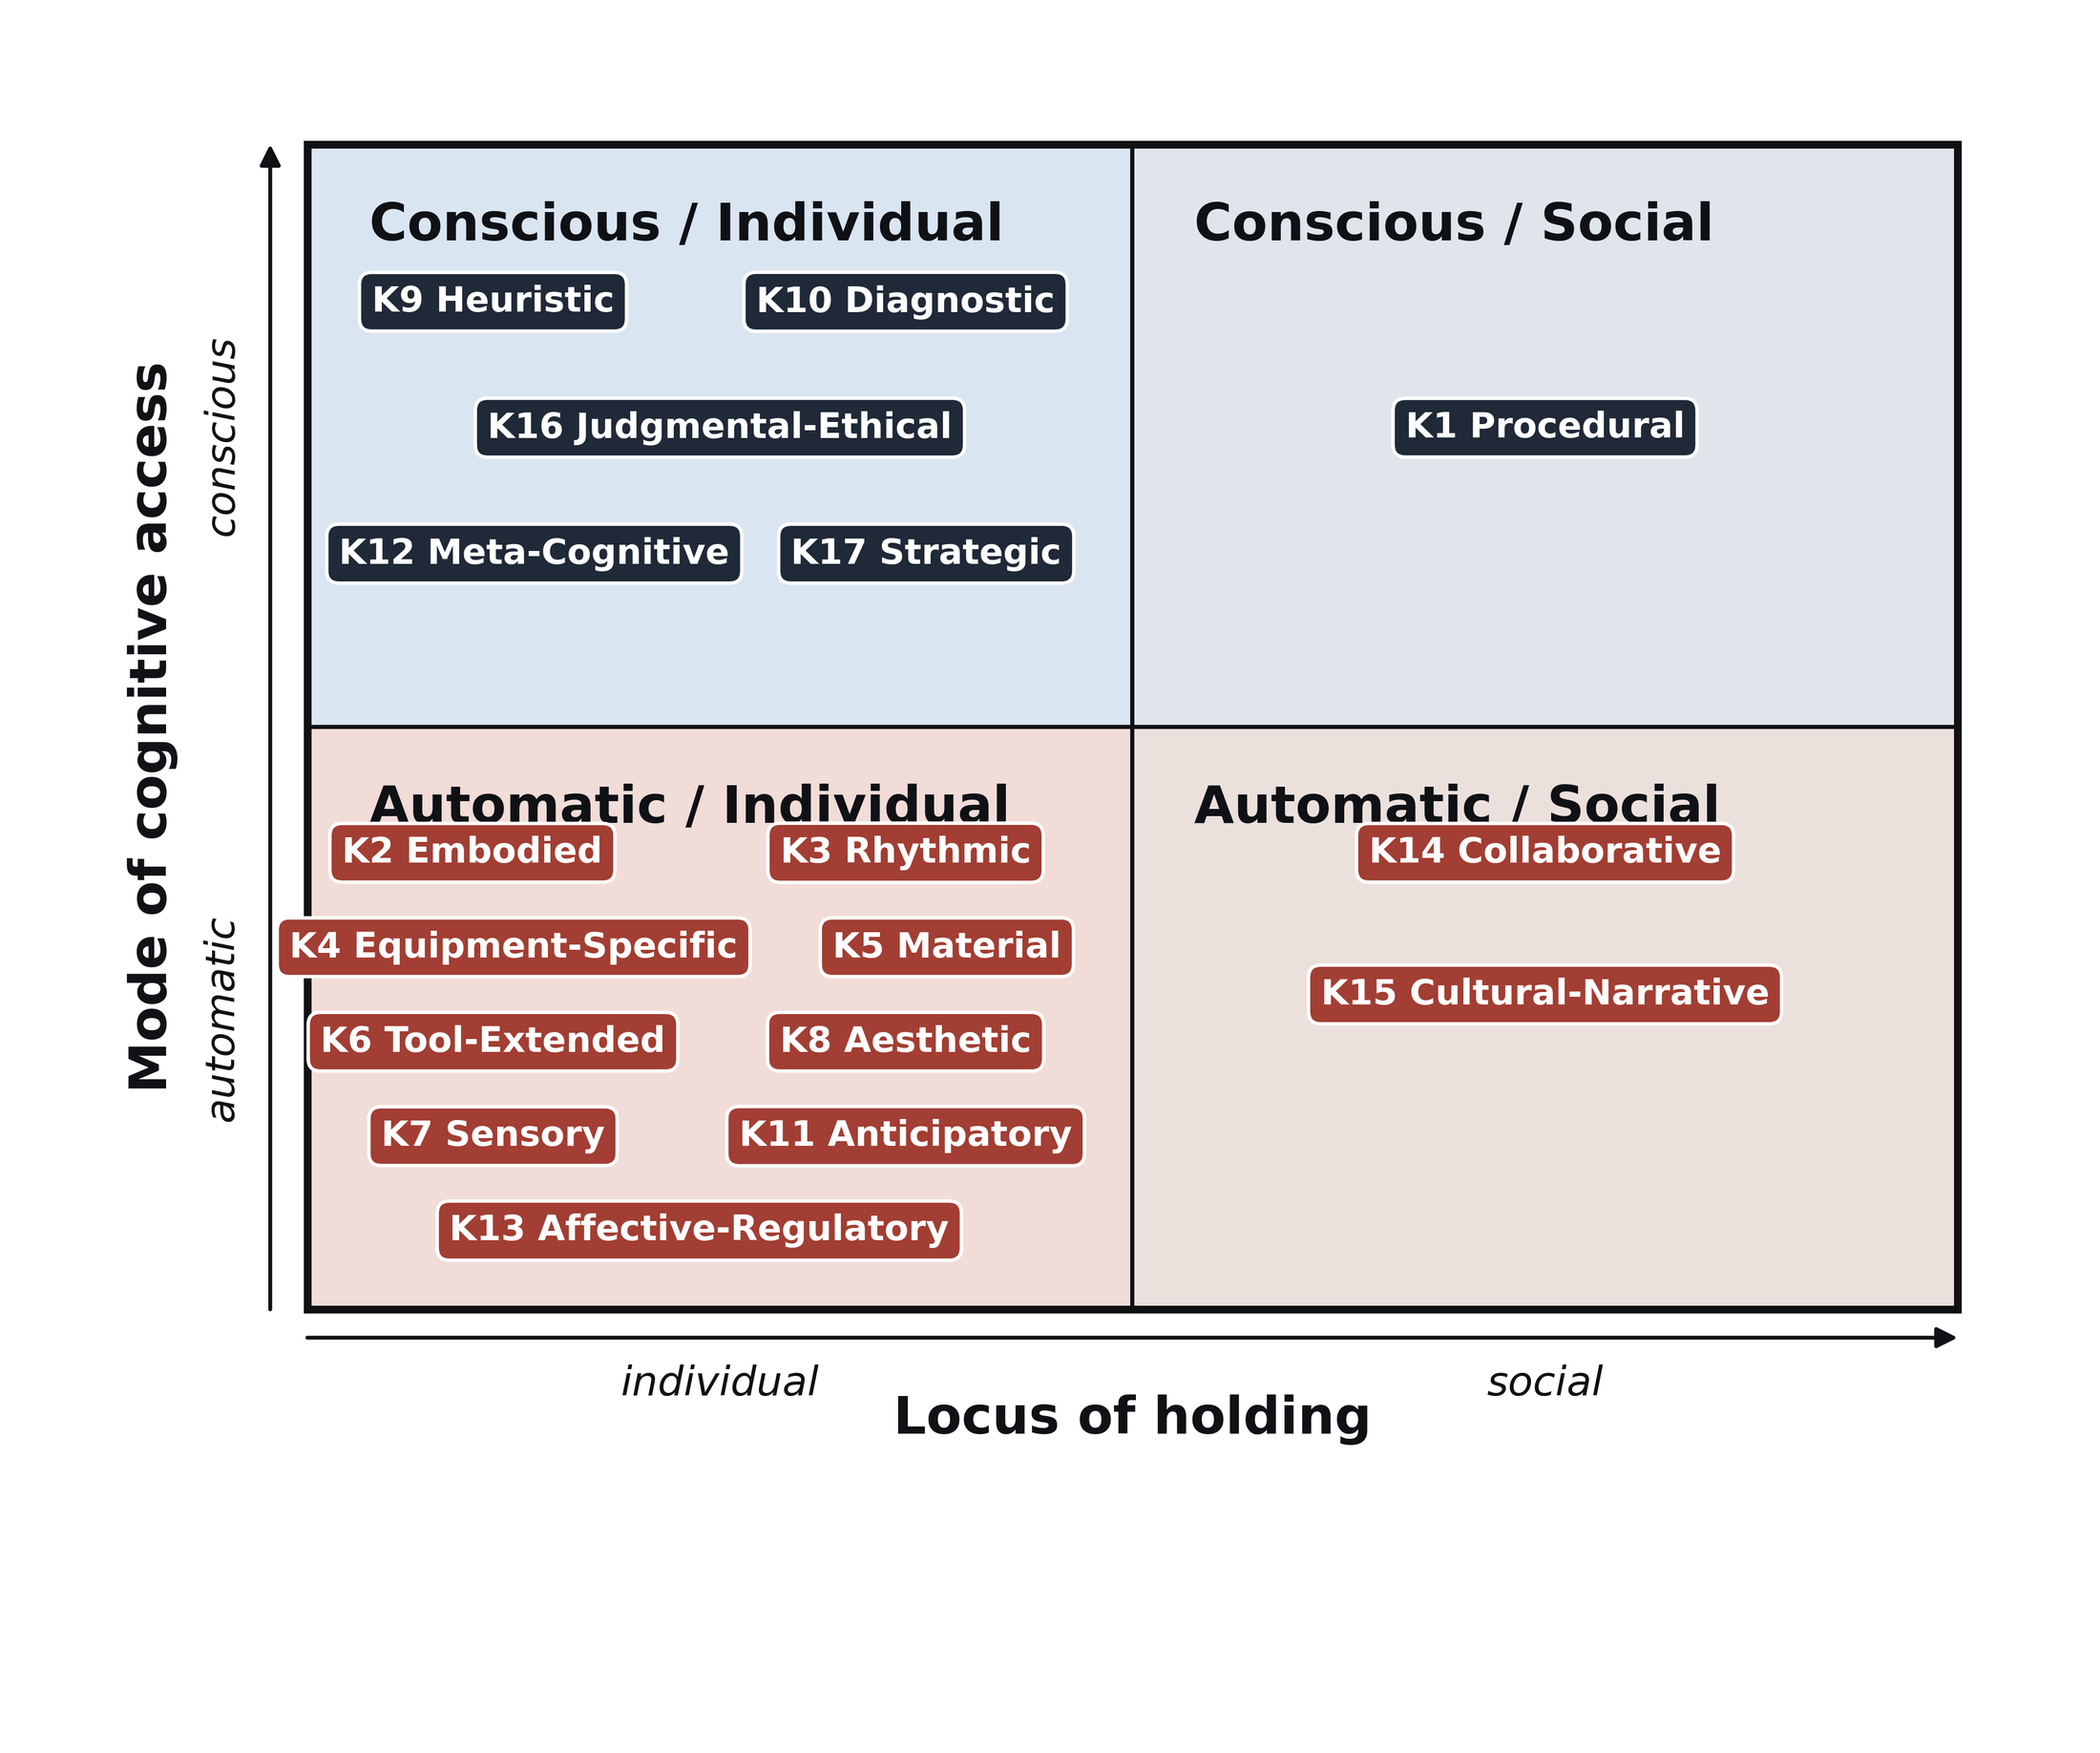
The taxonomy exists to prevent one specific failure, the universal capture method. In-flow observation works well for embodied and sensory categories and poorly for cultural narratives or strategic judgement, which need long-form interviews and cross-level review. A system that captures everything the same way will capture most of it wrong.
Metis carries a fragment from situated practice into governed memory
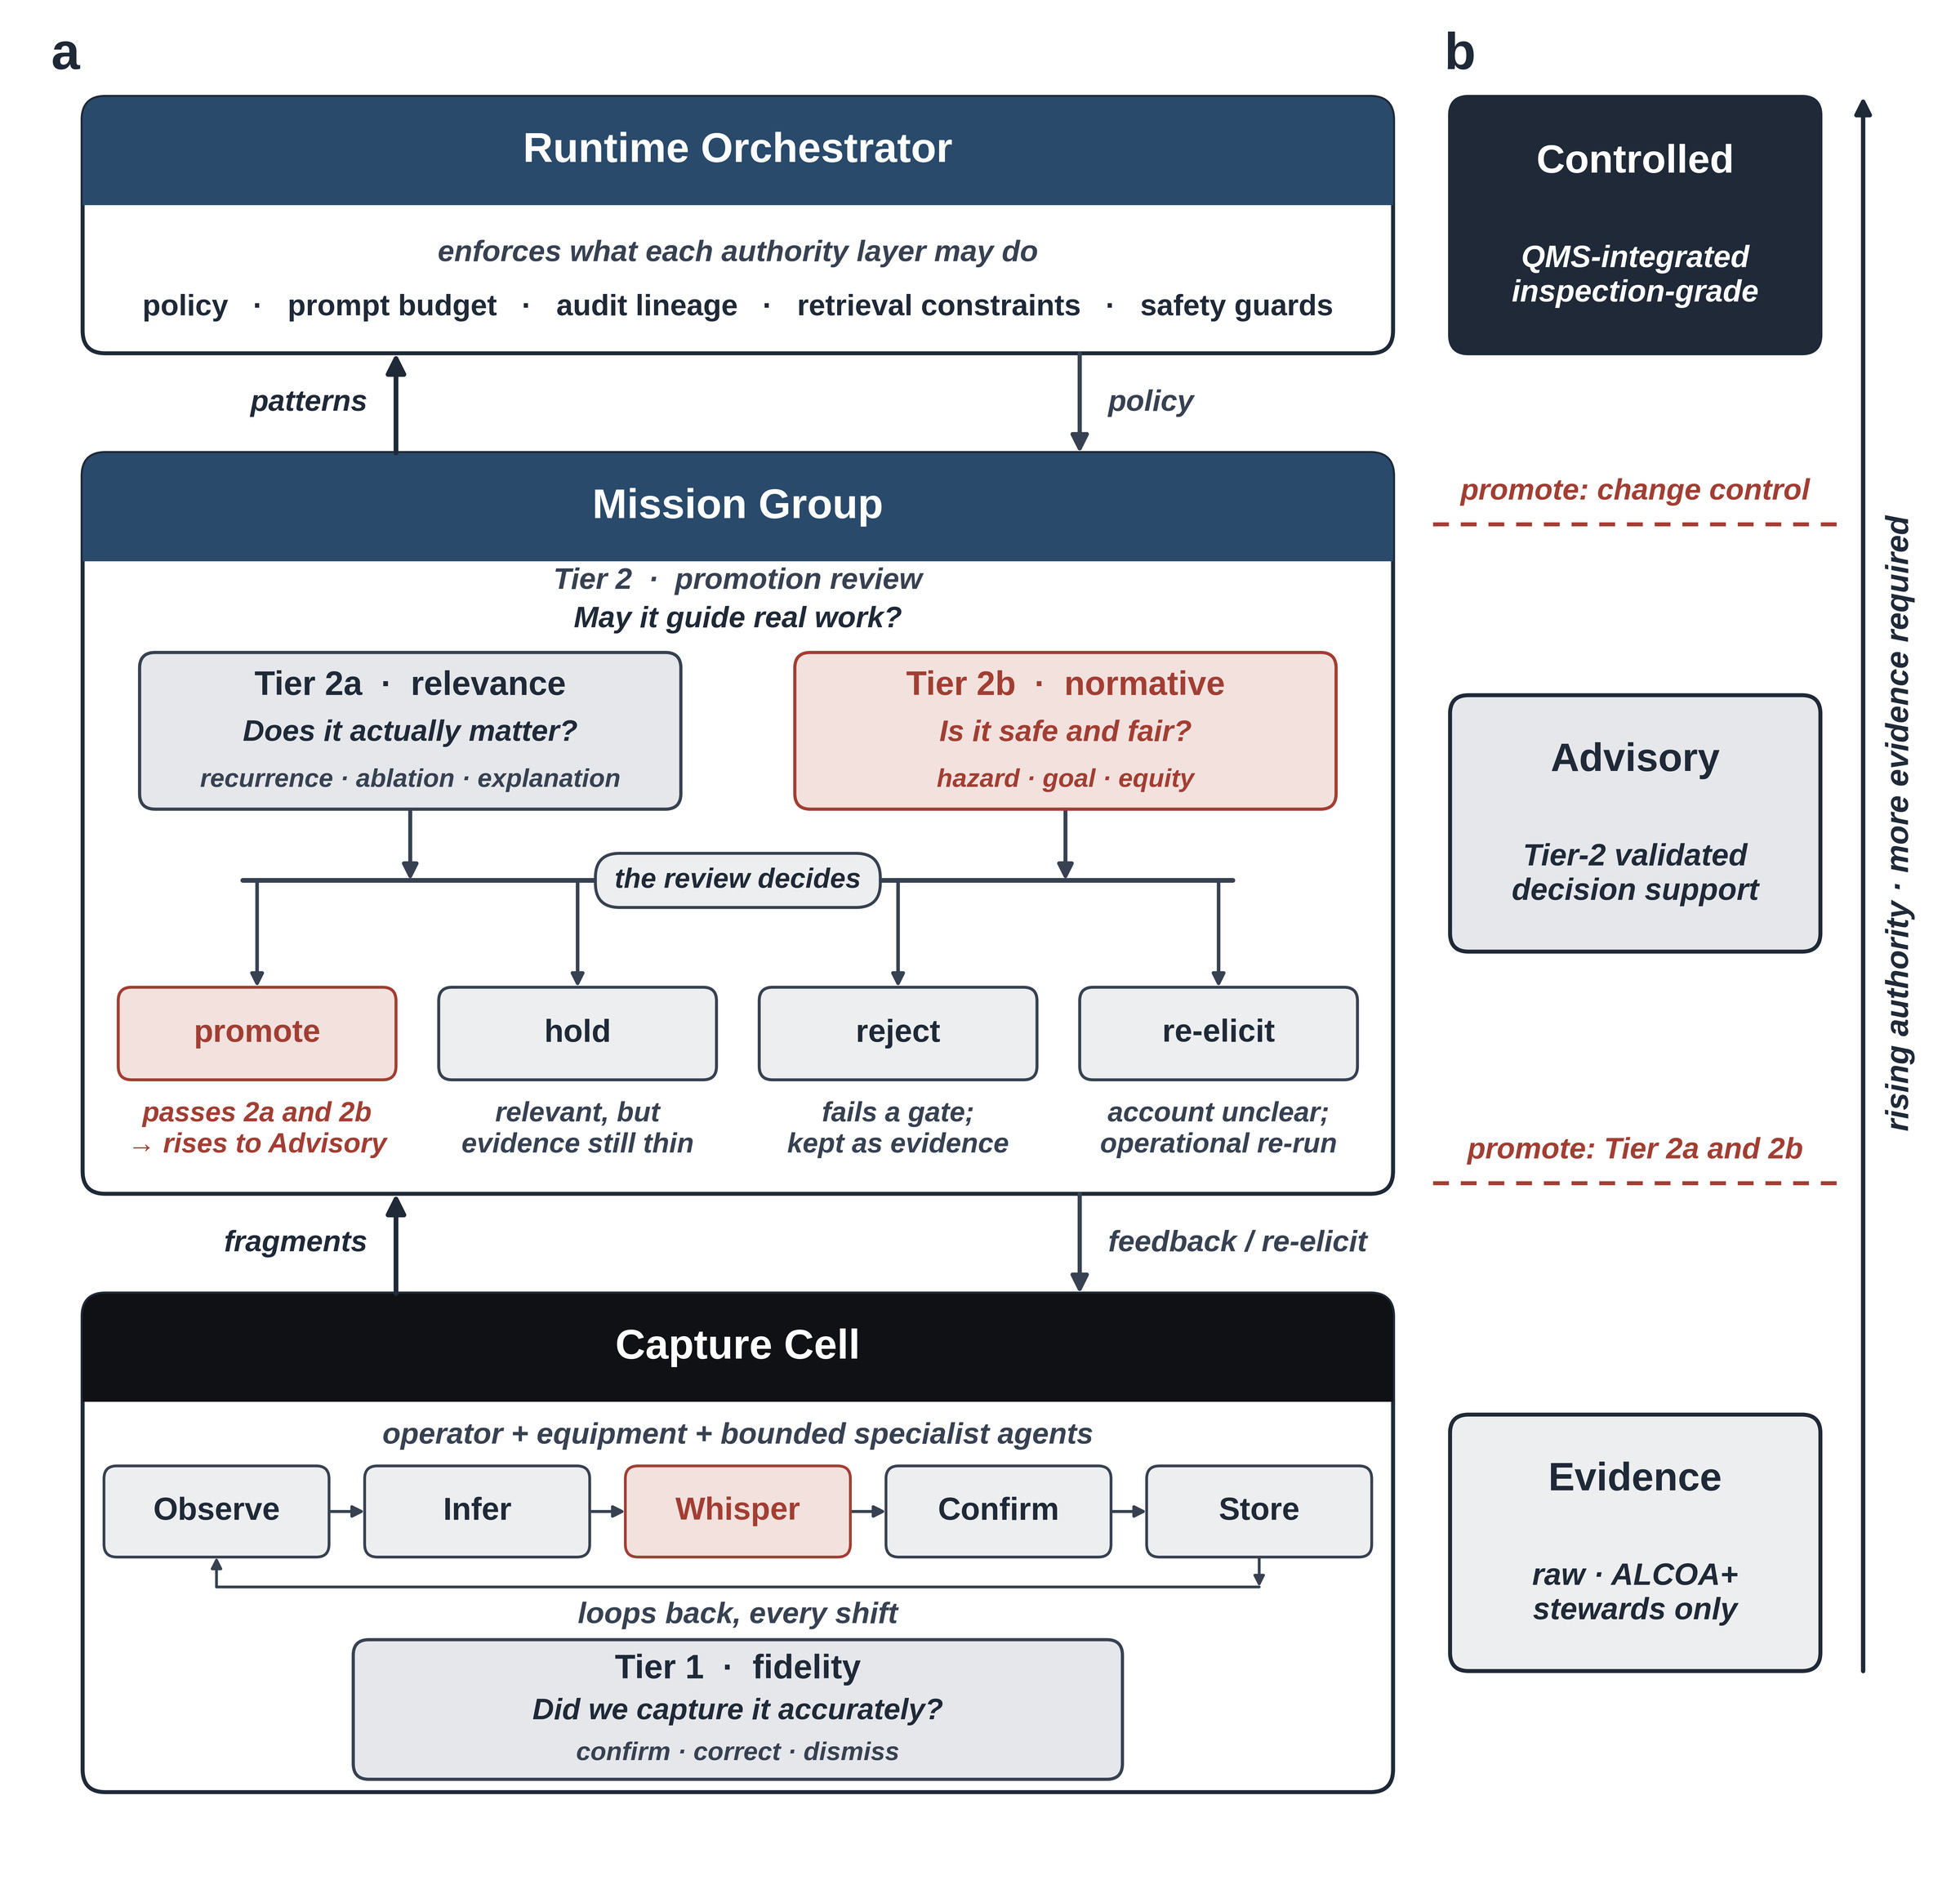
A schema tells you what a finished record contains. Someone still has to produce the record, check that it is faithful and safe, and limit what it may do. Metis assigns these three jobs to three separate organisational units, so capture, review and runtime enforcement remain separately accountable.
Metis is our reference architecture for that journey. The name comes from the classical Greek mētis, the situated, practical, cunning intelligence that James C. Scott argued formal schemes ignore at their peril.
The Capture Cell is the local hub, a worker or small team, the equipment or workflow in scope, and narrowly bounded agents that observe, infer, probe, confirm, and store. The Mission Group is the accountable review board. It examines candidate fragments across cells, weighs evidence, resolves conflicts, and decides promotion or rejection. The Runtime Orchestrator enforces policy, covering permissions, audit lineage, retrieval constraints, and escalation requirements.
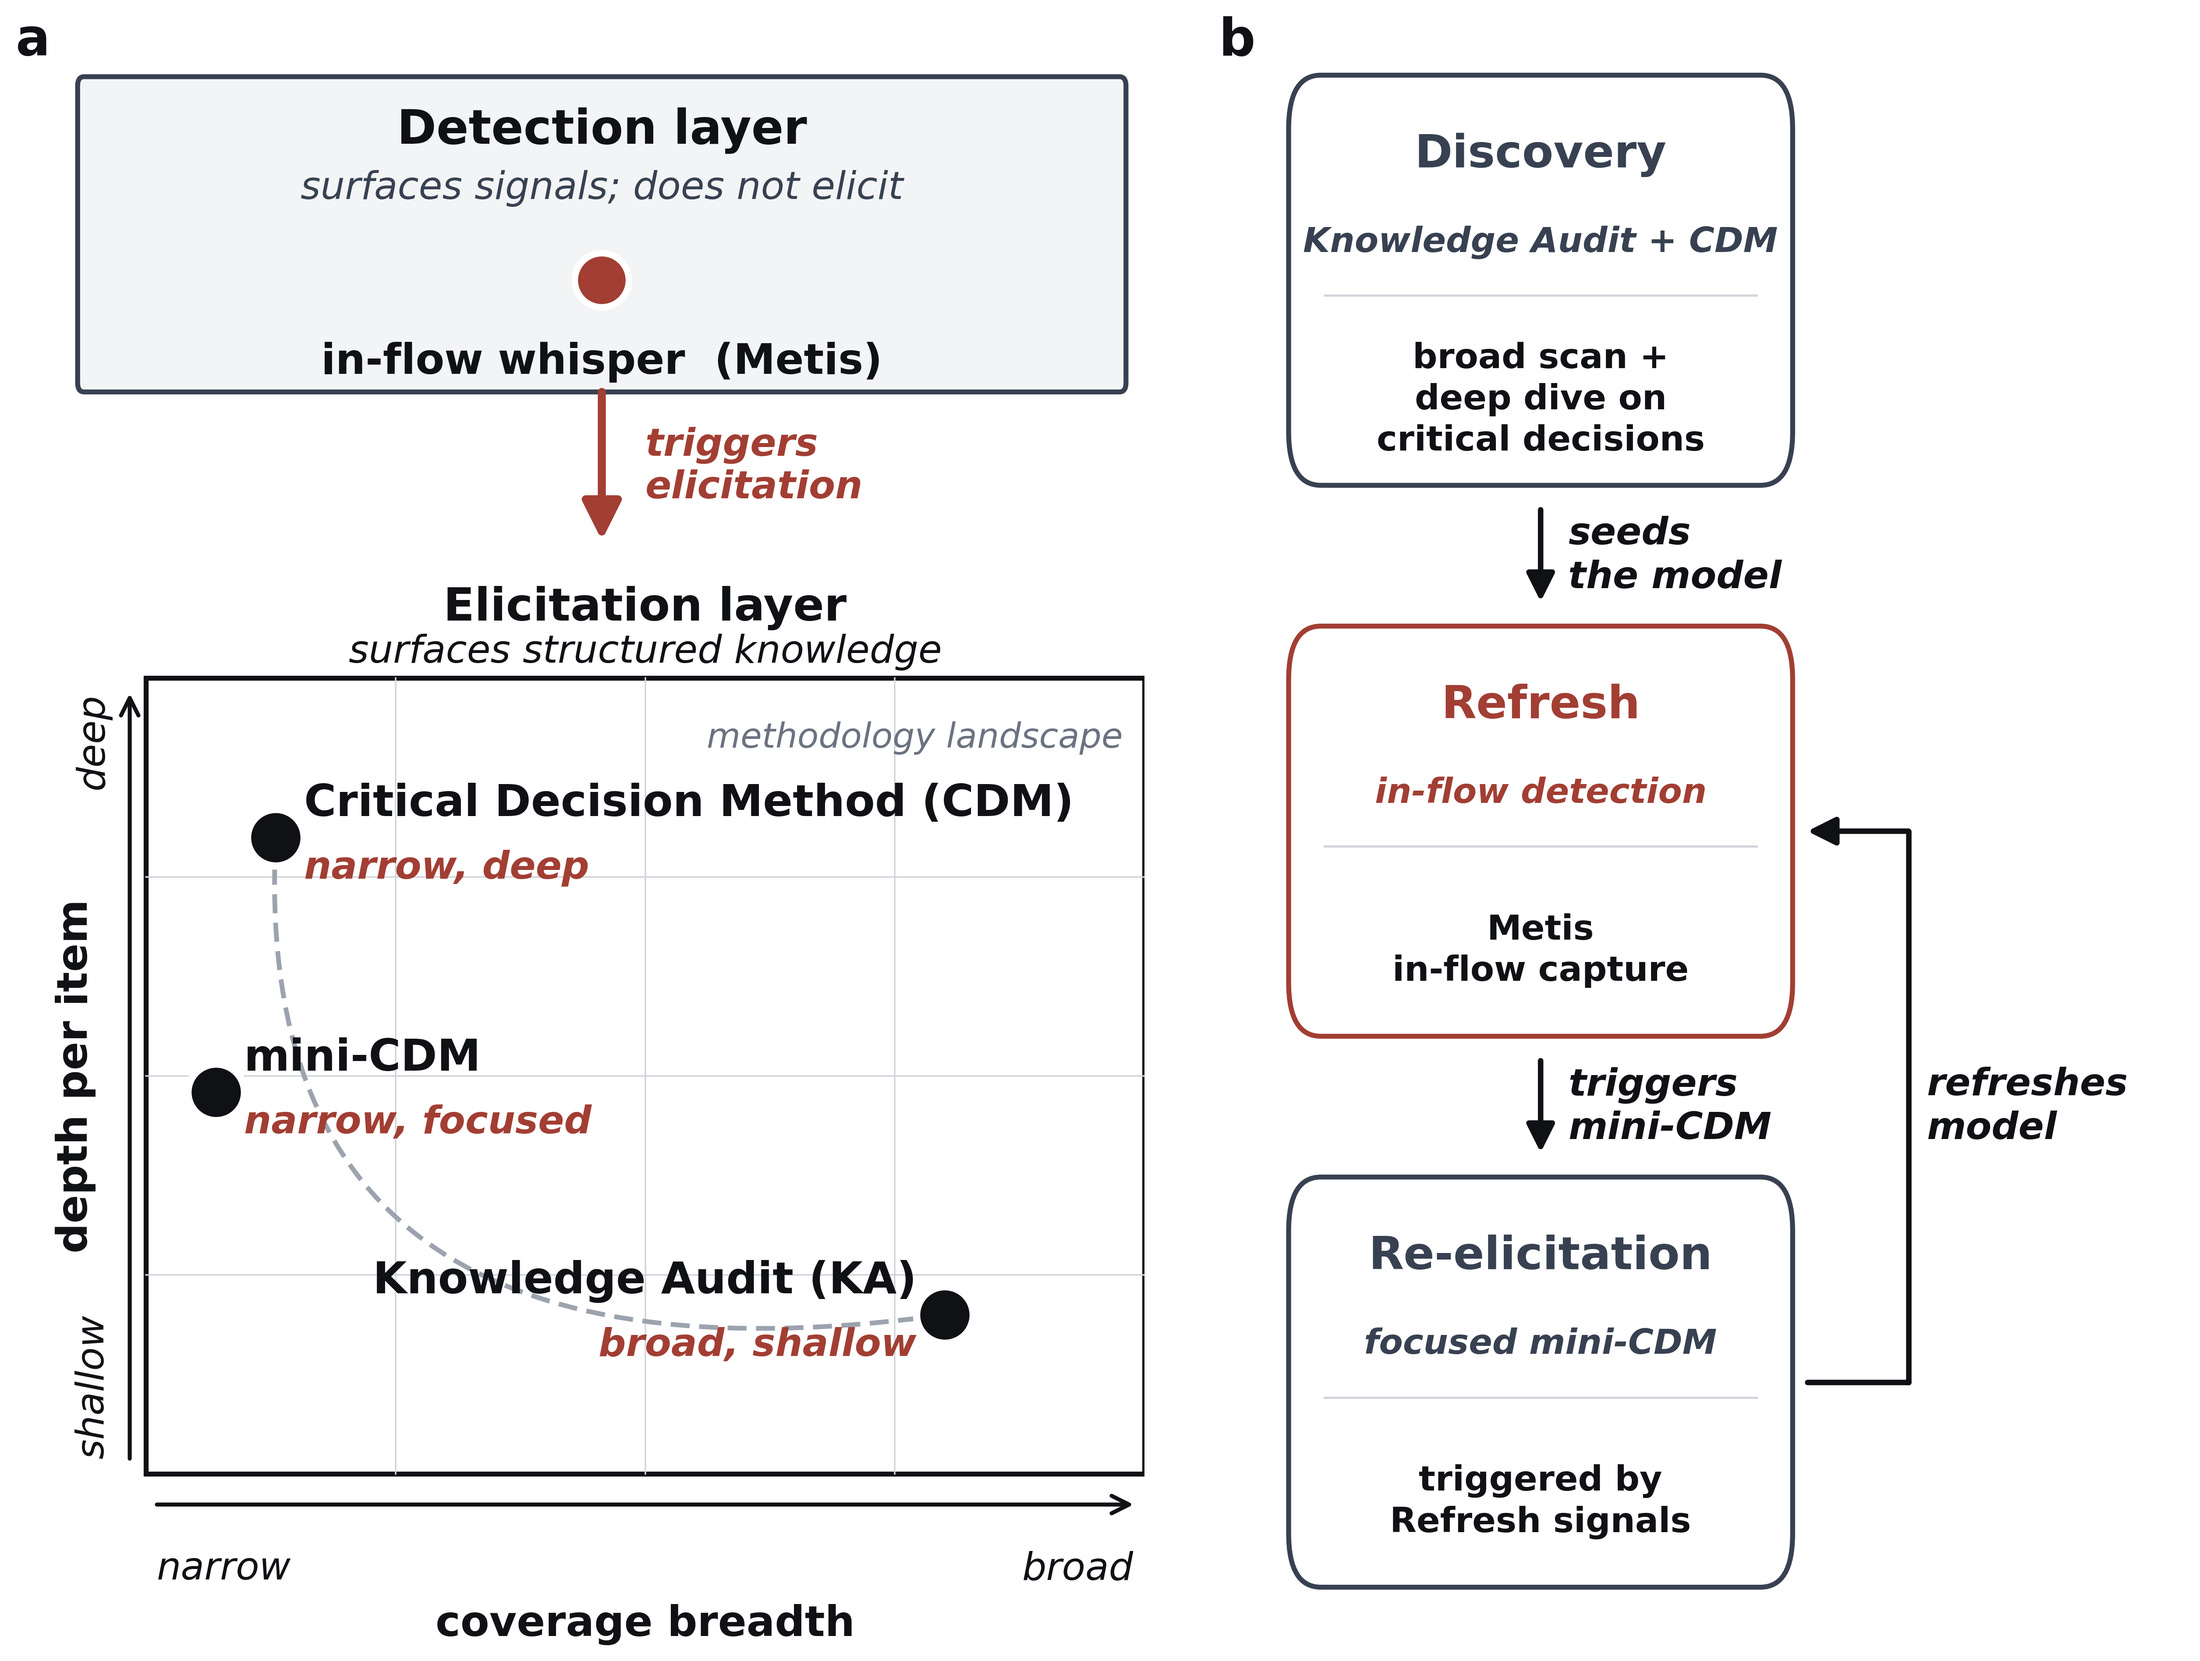
Capture itself splits into two activities that are usually run as one, and the split matters. Deep interviews can surface rich accounts but are too costly to run across every worker, decision and shift. Continuous detection is lighter than repeated deep interviews, but it yields signals rather than knowledge. Metis uses cheap, continuous detection to decide where costly, deep elicitation should happen. The detection instrument is the in-flow whisper. When a recurring pattern departs from what the procedure appears to expect, the system surfaces one short question at a natural pause, inside the interface the worker already uses.
A concrete example from the paper. In a quality-control laboratory, the procedure says accept any result inside the release limits, yet for one product the analyst routinely orders a re-run when a particular peak looks irregular, even when the numbers pass. The agent reads the review system, not the analyst, and notices the recurring re-run. After the analyst signs the batch record, one line appears in the same system. ‘You re-ran this product despite an in-spec result. Was the peak shape the reason?’ The analyst confirms and adds a sentence. That confirmed sentence, bound to the product, the instrument, and the analyst who gave it, is a candidate tacit fragment. No interview took place, the analyst lost a few seconds, and nothing guides any decision until the Mission Group reviews it.
Validation then runs in two tiers that answer different questions. Tier 1, local to the Capture Cell, asks whether the record says what the worker meant. Tier 2, in the Mission Group, asks whether the fragment has earned a role. It tests operational relevance through recurrence, ablation, and expert explanation, and normative alignment through hazard, goal, and equity review. The review ends in one of four outcomes, promote, hold, reject, or re-elicit. Rejection never means deletion; a rejected fragment remains governed evidence of what the organisation considered and refused.
Authority is a ladder with gates. The Evidence layer holds raw observations and hypotheses that can never influence a decision. The Advisory layer holds Tier-2-validated fragments restricted to conditional decision support. The Controlled layer holds fragments formally incorporated into procedures under change control. A fragment does not drift upward; it climbs only by clearing the named gate, and every move is recorded, justified, and reversible.
Retrieval closes the loop, and here Metis inverts the default of modern AI memory. Retrieval is conditional before it is similarity-based. The system evaluates a fragment’s conditions of applicability computationally and filters on them before any semantic ranking. Ask with the wrong equipment, the wrong operating mode, or a higher risk class, and the fragment is withheld with a recorded reason. When a situation falls outside every fragment’s stated envelope, the orchestrator escalates to human deliberation rather than returning a confident-looking precedent. Retrieval is a governance decision, not a search result.
All of this is built on CHAP, the Collaborative Human-Agent Protocol. Every whisper, confirmation, review, promotion, and retrieval lands on a hash-linked, append-only evidence chain that can be replayed and audited. The reference implementation is an open, local-first Python toolkit under Apache-2.0. It runs without cloud APIs or a GPU, and the demo runs the whole loop locally, writing a replayable evidence chain as it goes.
No full capture, no covert surveillance, no blind trust in experts
Tacit knowledge is never fully captured. Any translation into words, rules, or data is partial and loses practical meaning. The architecture enforces this by treating every fragment as bounded guidance rather than extracted truth. Metis can record observable traces of collective practice without claiming to represent the collective knowledge that sustains them. What enters the layer remains partial and situated.
A system that observes work is one design decision away from a surveillance tool. Metis therefore builds worker dignity into the record itself. Role-sensitive consent, attribution, visibility of captured material, contestability, and revocation travel with every fragment, and the reference implementation records no audio, video, biometrics, screenshots, or keystrokes. These requirements determine whether workers participate honestly, and honest participation determines whether the resulting memory can be trusted. The same discipline is what regulated environments already demand, from ICH Q10 and GAMP 5 to the EU AI Act, NIST’s AI RMF, and ISO/IEC 42001.
Expert judgement is calibrated to familiar conditions and can become unreliable when those conditions shift. Fragments inherit the limits and blind spots of their sources, so out-of-envelope situations should route to human deliberation rather than precedent.
Whether a governed tacit layer measurably improves operational learning, quality and resilience remains an open empirical question. The current framework is best suited to skilled, repetitive operational work with observable traces and natural pause points; strategic and creative work may require a different design. Knowledge ownership, worker compensation, labour relations and cross-site transfer also remain unresolved. The paper states 13 testable propositions and a research agenda; we intend to test them in the open.
What comes next
Metis starts from a narrow claim: small, fallible traces of expert practice can be recorded with the people, conditions and evidence that give them meaning. The empirical work comes next – whether agents using those fragments make better decisions, and whether organisations can capture them without turning learning into surveillance.
The paper accompanies this post as a PDF, and lives on Preprints.org (doi 10.20944/preprints202608.0927.v1).
The code is open at github.com/BrightbeamAI/metis, with an interactive demo and illustrated explainer in the repo.
The protocol underneath is CHAP, the Collaborative Human-Agent Protocol.
If your organisation runs on knowledge that has never survived being written down, we would like to hear what your experts know that your systems do not. Subscribe to follow the series.
References
Shahid, A., Suttie, G., Black, P., Garzón-Vico, A. (2026). Tacit Fragments: Operationalising Tacit Knowledge as a Governed Memory Layer for Agentic AI. Preprints.org, doi 10.20944/preprints202608.0927.v1.
Shahid, A., Suttie, G., Black, P. (2026). Collaborative Human-Agent Protocol (CHAP): An Open Protocol for Auditable, Structured Multi-Human and Multi-Agent Collaboration. arXiv 2606.09751.
Polanyi, M. (1958). Personal Knowledge: Towards a Post-Critical Philosophy. Routledge and Kegan Paul.
Polanyi, M. (1966). The Tacit Dimension. Routledge and Kegan Paul.
Ryle, G. (1949). The Concept of Mind. Hutchinson.
Dreyfus, H. L., Dreyfus, S. E. (1986). Mind over Machine: The Power of Human Intuition and Expertise in the Era of the Computer. Free Press.
Collins, H. M. (2010). Tacit and Explicit Knowledge. University of Chicago Press.
Tsoukas, H. (2003). Do We Really Understand Tacit Knowledge? In The Blackwell Handbook of Organizational Learning and Knowledge Management, 410-427. Blackwell.
Nonaka, I. (1994). A Dynamic Theory of Organizational Knowledge Creation. Organization Science, 5(1), 14-37.
Grant, R. M. (1996). Toward a Knowledge-Based Theory of the Firm. Strategic Management Journal, 17(S2), 109-122.
Spender, J.-C. (1996). Making Knowledge the Basis of a Dynamic Theory of the Firm. Strategic Management Journal, 17(S2), 45-62.
Klein, G. (1998). Sources of Power: How People Make Decisions. MIT Press.
Crandall, B., Klein, G., Hoffman, R. R. (2006). Working Minds: A Practitioner’s Guide to Cognitive Task Analysis. MIT Press.
Quine, W. V. O. (1960). Word and Object. MIT Press.
Wittgenstein, L. (1953). Philosophical Investigations. Blackwell.
Hollnagel, E. (2009). The ETTO Principle: Efficiency-Thoroughness Trade-Off. Ashgate.
Detienne, M., Vernant, J.-P. (1978). Cunning Intelligence in Greek Culture and Society. Harvester Press.
Scott, J. C. (1998). Seeing Like a State: How Certain Schemes to Improve the Human Condition Have Failed. Yale University Press.
Vaughan, D. (1996). The Challenger Launch Decision: Risky Technology, Culture, and Deviance at NASA. University of Chicago Press.
International Council for Harmonisation (2008). ICH Q10: Pharmaceutical Quality System.
ISPE (2022). GAMP 5: A Risk-Based Approach to Compliant GxP Computerized Systems, 2nd ed.
NIST (2023). Artificial Intelligence Risk Management Framework (AI RMF 1.0).
European Parliament and Council (2024). Regulation (EU) 2024/1689 (Artificial Intelligence Act).